When Instant Feedback Backfires
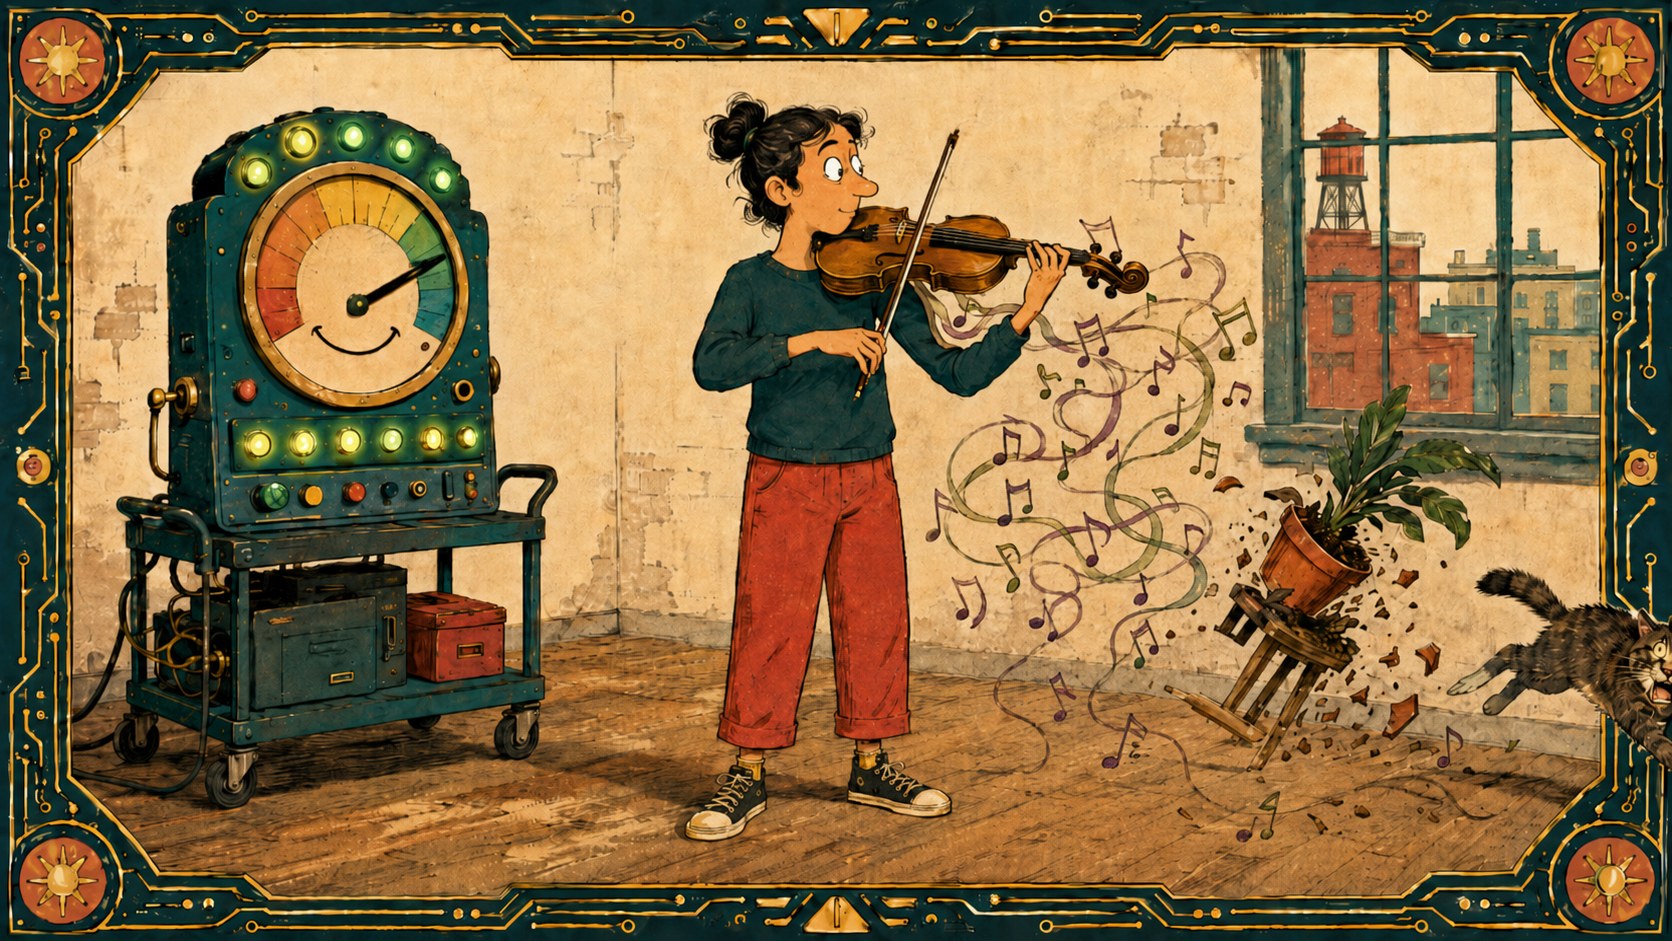
In 2021, researchers handed fifty people a violin and taught them to draw a steady bow. Twenty-four of them got real-time feedback while they played, on their bowing motion and on the sound they were making. The feedback worked. Their bowing improved.
Their sound got worse.
That result, from a randomized controlled trial published in Frontiers in Psychology, is the most useful cautionary evidence in the whole field of AI-assisted music practice, and it has almost nothing to do with the technology failing. The technology did precisely what it was built to do. The problem was in what it was built to do.
This is worth understanding properly, because the same mechanism sits inside any practice app that scores one part of your playing, which is most of them, and it is rarely explained to the people using one.
What the study actually did
Fifty participants, none of whom had ever played the violin, were split into two groups. Twenty-four of the fifty received real-time visual feedback while they practiced, delivered in two separate conditions: one that showed them their bowing motion, and one that showed them a measure of their sound quality. The other twenty-six practiced the same material with no display at all. Both groups were learning the same skill: how to draw a bow that produces a steady, controlled sound.
The task is a good choice for a study like this, because bowing is easy to measure. A bow stroke has a speed, an angle relative to the bridge, a distance from the bridge, and a degree of straightness. All of that is geometry, and geometry can be tracked by a camera and turned into a number on a screen in real time.
Sound quality is the harder thing to put on a screen. This study did put it there, using an acoustic measure of tone, but it remains the outcome the geometry is supposed to produce rather than a movement you can reach out and correct.
During the practice sessions, the feedback group’s bowing kinematics improved compared to the control group. The measured thing got measurably better, exactly as designed.
At the same time, the sound quality of their playing deteriorated. That happened under both feedback conditions, including the one where sound quality was the number on the screen. The authors attribute it to divided attention: reading a live display while learning a new physical skill leaves less of the learner available for the playing itself.
There is a second half to this and it matters a great deal. At the transfer test later, the feedback group controlled the dynamics of their sound about ten percent better than the control group, and that was the only difference between the groups that reached statistical significance. Pitch stability and the other sound descriptors did not separate them. So the cost during practice did not stick, and what the training left behind was one measurable advantage rather than a general improvement in sound.
So this is not a story where the tool was bad, and it would be dishonest to tell it that way. The tool worked. It is a story about a cost that appeared partway through, lasted a while, and would have been completely invisible to anyone looking only at the metric the tool reports.
Where the sound went
Feedback is not neutral information sitting quietly in the corner waiting to be consulted. It is a hand pointing at something, and attention follows the point.
Put a live readout of bow angle in front of a beginner and their eyes go to the readout. That is not a character flaw, that is how attention works under load. The readout is unambiguous. It updates instantly. It tells you, without hedging, whether you are winning. Your own ear at that stage is slow, uncertain, untrained and full of doubt. Given a confident source and a doubtful one, people take the confident one.
So the beginner optimizes whatever the display is reporting at that moment. Their arm gets straighter, because straightness is the thing that turns the indicator green. A live measure of tone is still a measure, and watching one is a different act from listening, which is why the sound-quality display offered no protection. Attention went to the screen whichever quantity was on it, and the ear was what got left out.
This is the practical version of a distinction we drew in what AI can actually hear when you practice. Pitch, rhythm, timing and physical geometry are measurable with real accuracy. Phrasing and intent are not, and a tone number, as the trial showed, is still something you watch rather than hear. A system built around the measurable parts of playing does not simply give you most of a teacher. It quietly reorganizes your practice around what it can display, and everything outside the display gets whatever attention is left over, which for a beginner under load is usually none.
How far this goes beyond violin bows
It would be easy to file the 2021 trial as a curiosity about one narrow task with novice players. It is a narrow task with novice players, and any honest reading has to say so. Whether the mechanism travels is a separate question, and the honest answer is that the direct evidence for it is thin. There is this trial, in which divided attention was the authors’ own explanation for the result. There is the February 2026 systematic review below, which found a different mechanism running over months, motivational rather than attentional, arriving at a similar outcome. Everything past those two is extrapolation, and it is worth labeling as extrapolation rather than presenting as a settled finding.
A 2026 review in Discover Education focused specifically on instrumental music education lists constraints in expressive feedback among the field’s central open problems, alongside dataset bias and limited cultural sensitivity, and concludes that hybrid models combining human and machine instruction are the defensible ones. That review reports nothing about attention and should not be read as though it did. What it does establish is the boundary the attention problem operates inside: expression is the thing these systems are worst at reporting on, so it is also the thing a learner gets no signal about. When a system tells you that something was wrong but cannot tell you why, you are left to guess at the cause, and people guess in the direction of whatever the system seems to be watching.
If the mechanism does travel past a beginner and a bow, this is the shape it takes wherever feedback is narrow and fast:
You play a passage cleanly at a slower tempo because the app is checking accuracy, and you never discover whether the passage had any shape to it, because shape was not on the list.
You breathe in a musically wrong place because the timing readout goes green when you do.
You stop using rubato, the small elastic pushing and pulling of tempo that makes phrasing sound human, because the system counts it as drift.
You practice the passage the app flags rather than the passage that is actually holding you back, because one of them produces a visible score change and the other produces nothing.
None of these are the app malfunctioning. Every one of them is a person correctly doing what they are being graded on. That is not a bug in the learner. It is the predictable result of putting a narrow live measurement in front of somebody and calling it feedback.
The slow version: score-chasing
The 2021 trial caught this inside a single session. A systematic review of 21 empirical studies published in Frontiers in Psychology in February 2026 describes something slower and different in kind. It did not measure attention, so it is not evidence that the divided-attention effect travels beyond the practice room. What it found is a set of motivational and evaluative mechanisms that arrive at a similar place over months, and it gives each of them a name.
The review followed PRISMA, the standard checklist for systematic reviews, across four databases and looked specifically at how AI tools shape learners’ beliefs about themselves and their sense of agency. It found real benefits, which we will come to in a moment. It also identified four distinct ways that support turns into something less healthy.
Two of them are the long-form version of the bowing problem. Score-driven goal distortion is what happens when a learner’s goals gradually bend toward whatever the system rewards. Algorithm-accommodating self-censorship is the next stage, where they begin shaping their playing to satisfy the system rather than to sound good, editing out the things it marks down even when those things were musically right.
The other two are about judgment rather than goals. Learners outsource evaluative authority, handing over the decision about whether something was good. And their confidence undergoes an attributional shift, becoming tethered to the presence of the tool, so it drains away when the tool is not there.
The review also found that the type of AI matters. Assessment-oriented tools, the ones that score your playing, most consistently strengthened learners’ beliefs about their own ability through clear visualized feedback, and supported the habits of self-monitoring and self-reflection. That is a genuine benefit and it is the thing practice apps do best. But it is also the category most likely to produce score-chasing, for the same reason: a clear number is persuasive, and persuasive things get followed.
One more finding is worth holding onto, because it complicates the easy story. There is a chapter in The Oxford Handbook of Artificial Intelligence in Music Education, published in August 2026, on motivation and AI in music learning. Its authors describe it as drawing on a literature review and an exploratory study of their own, and they report that students’ engagement with AI tools generally was driven more by extrinsic demands than by intrinsic interest in artistic exploration, and that the tools were used mainly for academic rather than musical purposes. Their subject is AI tools across the board, much of it generative, rather than practice-scoring apps in particular, so read it as a description of the climate a scoring app arrives into. Where the motivation to use a tool is already extrinsic, the pull toward optimizing whatever it scores is stronger, not weaker.
What the technology is genuinely good at
None of the above is an argument for practicing in the dark.
A chapter in the same Oxford handbook, by Cornelia Fermüller and Irina Muresanu, describes a violin platform combining computer vision, audio analysis and reinforcement learning to give feedback on posture and bowing motion. Their framing is that this reduces the geographic and economic barriers that keep people away from good instruction, and extends what a teacher can do across the week. That is a real benefit and it is the honest case for this technology.
A beginner genuinely cannot see their own bow angle. They cannot feel that their wrist is collapsing, because the collapsed position feels normal to them. A camera can see it on Tuesday, when no teacher is in the room. The 2021 trial did leave one lasting advantage behind, the dynamics result described above. The paper does not break that result out by condition, so the honest reading is that information a learner has no other way to get left its mark on the sound rather than on the mechanics.
The question is never whether to use feedback. It is what job you have given it, and what you have kept for yourself.
A practice protocol that keeps your ear in the loop
The fix for all of this is unglamorous. It is one deliberate split in how you spend a session, plus a few habits that keep your own ear doing the judging.
Separate the two modes deliberately. Drill with the feedback on. Bow angle, intonation, rhythmic accuracy, whatever you are working. Let it be relentless about the mechanical layer, which is what it is good at, and do not feel bad about following it closely. That is the point of it.
Then turn it off and play the passage. No screen. No score. Nothing to win. Ask yourself one question, and make it the right question: not was that accurate, but did that sound good. Those are different questions and only one of them is being asked by your app.
Do this every session, not occasionally. The judgment muscle is the one at risk of going unused, and it atrophies quietly. Five minutes of playing with nothing measuring you is a small price for keeping the thing that eventually makes you a musician rather than an accurate player.
Record yourself regularly. Recording is an old feedback tool and still one of the best, because of a property it has that a readout does not: it gives you information while leaving the judgment with you. You listen, you decide. Nothing tells you whether you won.
Check which passage you are practicing and why. If you are spending your week on the bar the app flags rather than the bar that is actually holding the piece back, something has gone sideways. This is worth thinking about alongside the wider question of how to practice at home productively.
Bring the ambiguous cases to a lesson. A passage that scores well and still sounds wrong is a genuinely interesting problem, and it is exactly the problem a good teacher is there for: they can usually name the cause quickly, where a scoring system can register that accuracy and sound disagree but cannot tell you why. If your playing has stalled in a way you cannot name, the same logic applies to what to do when you plateau.
What a teacher is doing that the readout is not
It is worth being concrete about the difference, because “human judgment” is a vague phrase that gets used to mean nothing in particular.
A teacher listening to you play a phrase is doing several things at once that no current system does. They are hearing the sound in the context of the piece, the style, and the composer’s intentions. They are deciding which of your five simultaneous problems to mention, because mentioning all five would be useless. They are tracking whether you are frustrated, bored, tired or on the edge of a breakthrough, and adjusting what they say accordingly. They are remembering what you sounded like a month ago. And they are making a judgment about whether the technically wrong thing you just did was actually more musical than the technically right thing would have been.
The 2021 trial is, in a sense, a study of what happens when nobody is doing that job. The bow got better, the sound got worse, and it took the researchers setting the two results side by side to show what the trade had cost. Nobody in the room was weighing one against the other while it was happening, which is the job described above. A display can report on tone. What it cannot do is decide that tone was the thing worth protecting this week, or notice that a learner has stopped listening while they watch.
Where we sit
Tunelark uses AI across our own daily operations and we are building it into what we make. Our practice games are technology rather than AI, using structured progression and mastery checks so a student has something concrete to work on between lessons, and AI features may join them in time. On the lesson platform itself, keeping AI in a support role around a live teacher is the direction we are building toward.
The reason a live teacher stays at the center of every lesson is on display in this study. Something has to be listening to the whole performance rather than the scoreable part of it, and right now that something is a person.
The bottom line
More feedback is not automatically better feedback. A live readout pulls your attention toward whatever it is showing and away from everything else, and it will never tell you that is happening. The risk lies in where your attention goes, not in which quantity somebody chose to put on the screen, so picking a better quantity to display does not solve it.
Use it for what it measures, which is real and worth having. Keep your own ear in the loop on purpose, because nothing in the tool will remind you to. And if you want the wider picture of where the evidence lands, we covered whether AI can replace a music teacher in its own article.
How to Find a Music Teacher on Tunelark
Tunelark connects you with deeply vetted music teachers who teach online across piano, guitar, voice, violin, drums and more. Vetting is run by working musicians and music teachers, not a general recruiter, and every teacher sets their own rate and shows it on their profile. Scheduling, billing and support are handled for you.
- Browse teachers for your instrument at tunelark.com/find-a-teacher.
- Read their bios and watch their videos to see how they teach.
- Book a trial lesson with the one who sounds right for you.
- How you feel afterward is the thing no system can measure for you.
Frequently Asked Questions
Can real-time feedback make my playing worse?
It can make one part of your playing worse while improving another. In the 2021 violin trial described above, measured bow motion improved while sound quality declined in the same sessions, which the authors put down to divided attention. The cost showed up during practice and did not carry through to the transfer test.
Should I use a practice app at all?
Yes, for the things it measures reliably, and with your own listening kept deliberately in the loop. The problem is not the tool. It is treating its score as the whole picture of how you played, when it is a report on the measurable parts of your playing and silent on the rest.
Why does my playing sound worse when I focus on technique?
Because attention is limited and whatever is being measured takes most of it. This is a normal stage rather than a sign you are doing something wrong. It resolves faster if you alternate: drill the technical element with feedback on, then play the passage with everything off and listen to the result.
Is an AI score an objective measure of my playing?
No. Any automated assessment encodes choices about what to measure, what counts as correct, and how different aspects get weighted. A high score means you did well on the things it checks. That is genuinely useful information and it is not the same as playing well.
How do I stop chasing the score?
Separate the sessions. Use the tool while drilling, then turn it off and play for your own ears with nothing to win. A 2026 systematic review of 21 studies found learners bending their goals toward whatever the system rewarded and editing their playing to satisfy it, and the practical fix is to spend regular time where there is no reward to bend toward.
Does this mean real-time feedback is bad for beginners?
No, and the trial’s transfer result argues against it. Beginners often cannot perceive the thing they are doing wrong, so external information is valuable precisely when self-monitoring is weakest. The risk is not the feedback, it is the feedback being the only voice in the room for six days at a stretch.
Keep reading
About Jennifer Heath
I'm Jennifer Heath, VP of Operations at Tunelark and a lifelong singer. I joined the company in 2020 and oversee much of what makes Tunelark work for students and teachers: hiring, training and supporting our instructors, student support, marketing and day-to-day operations. I started voice lessons at 7 and sang with touring choirs through my teens. Music belongs in every life, for the self-expression, the discipline, the comfort and the simple joy of it.